

Layers list
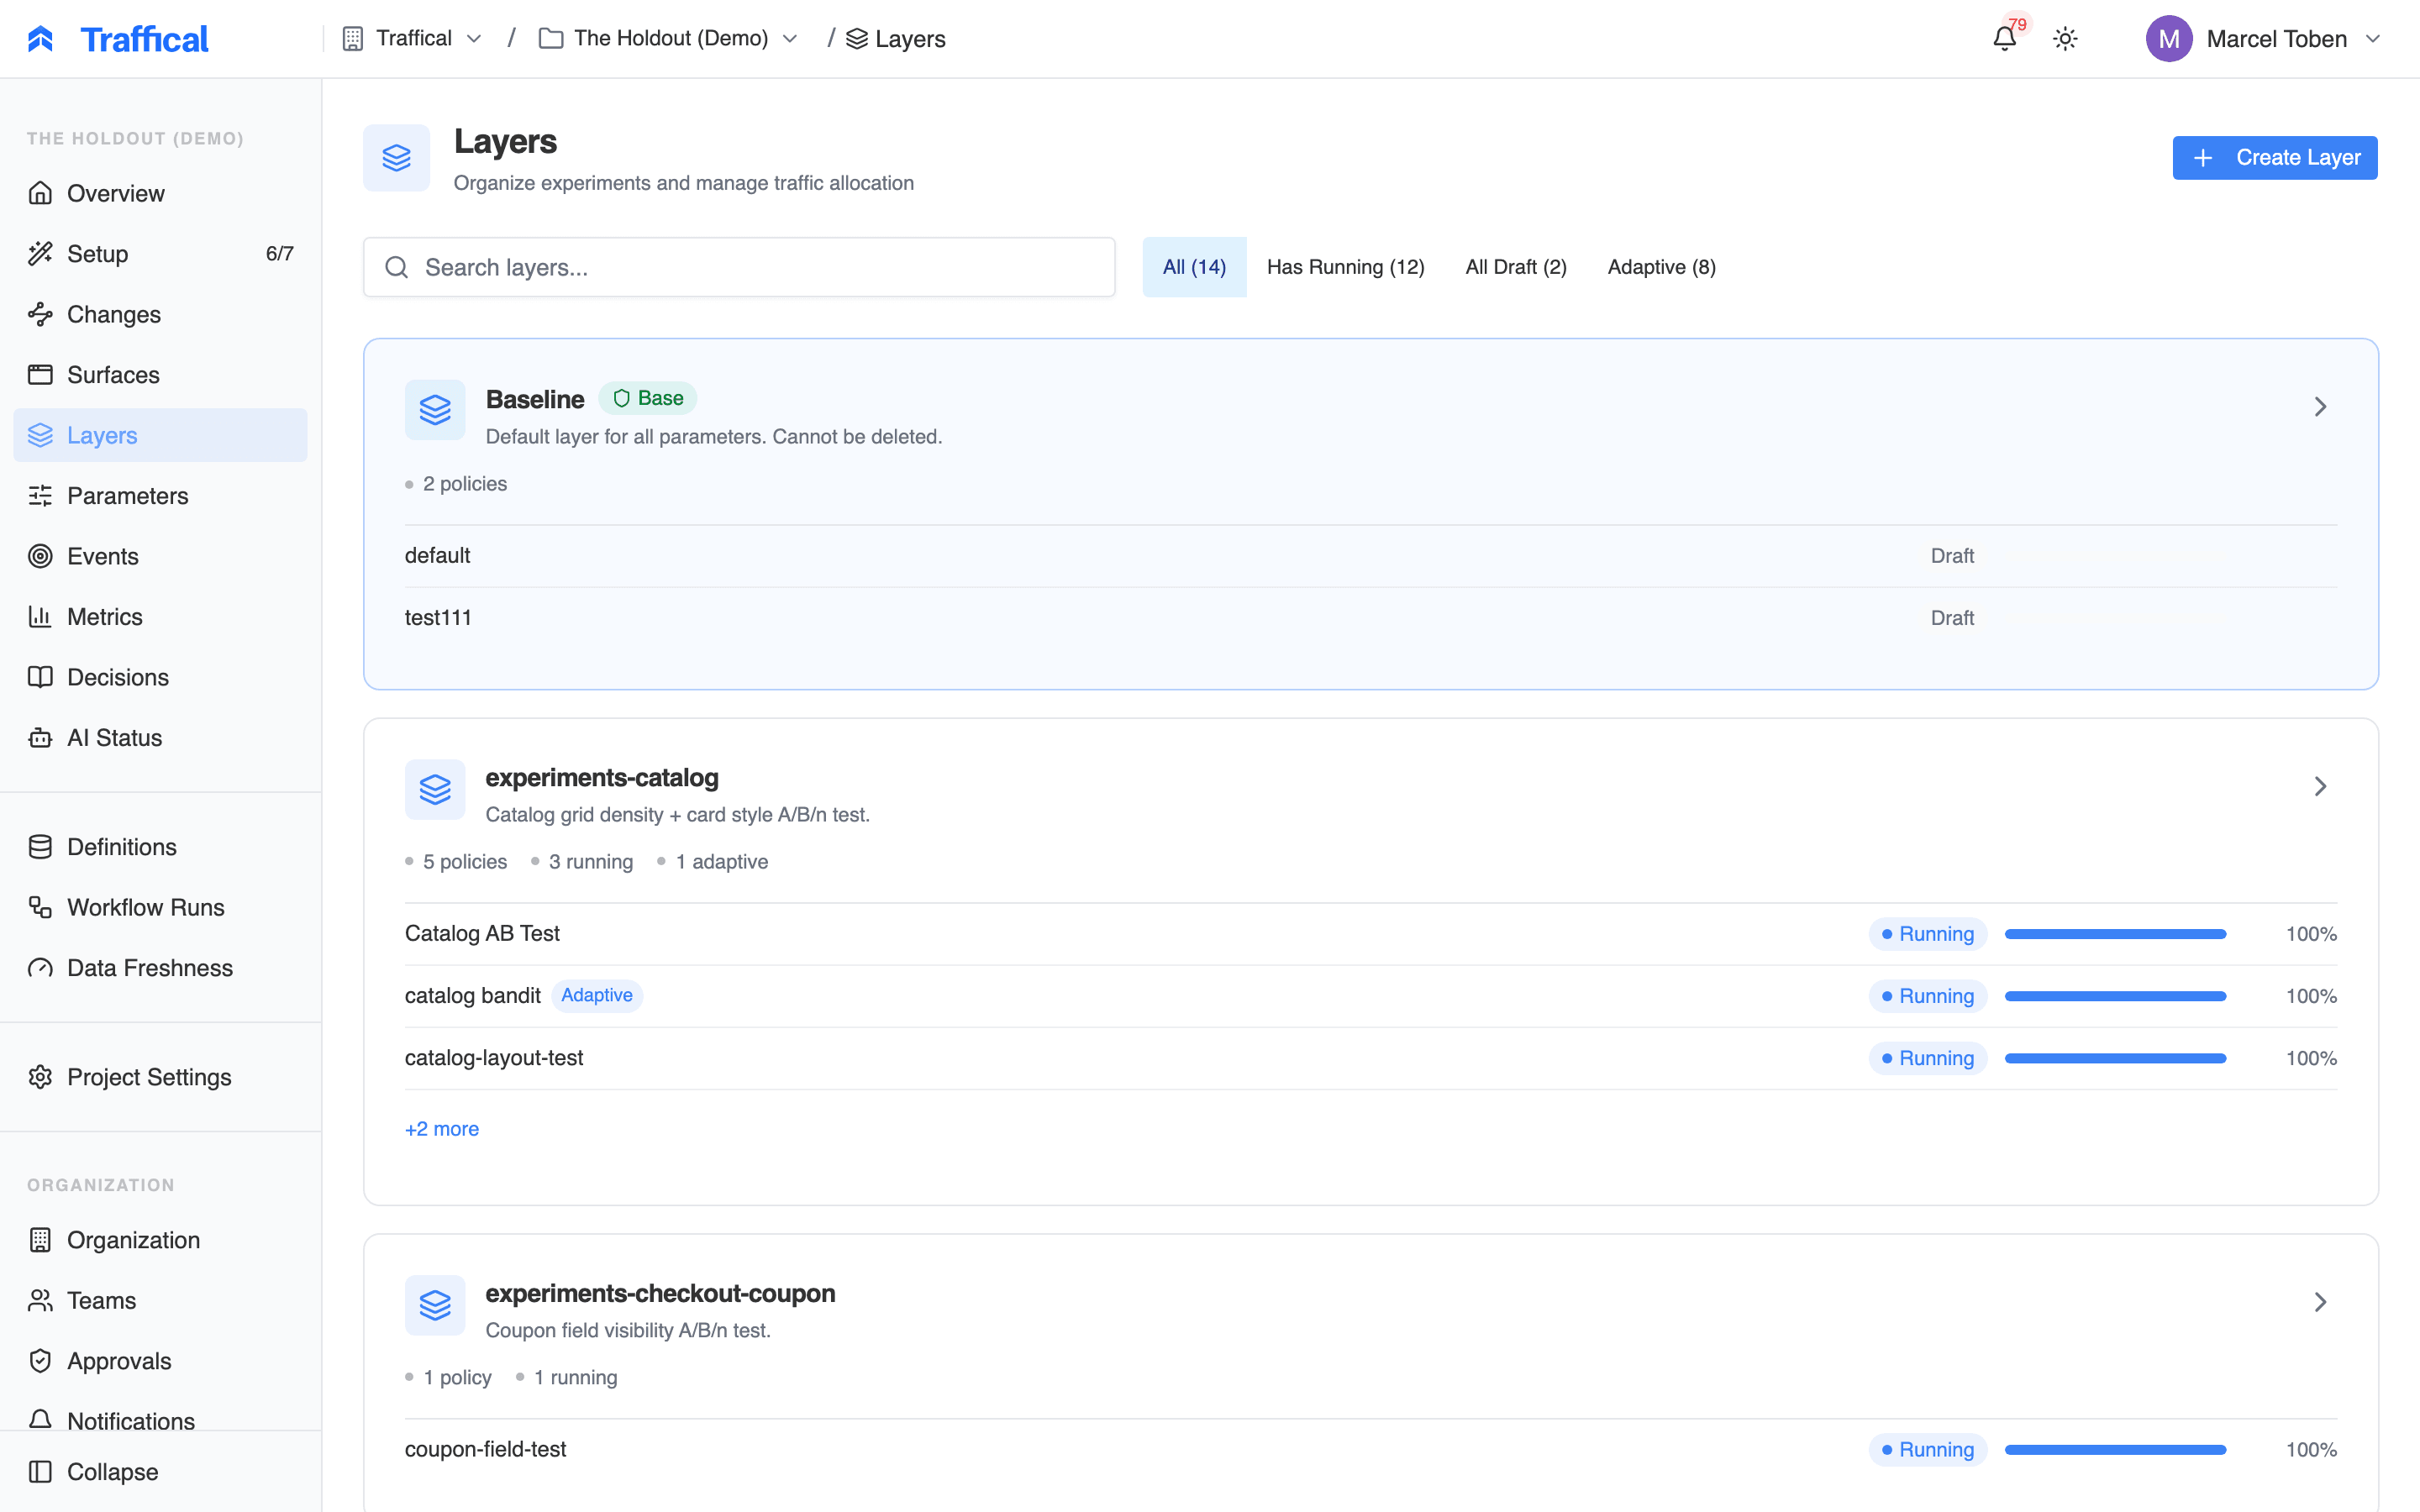
The layer list
Each card is a layer with its policies at a glance:- Name and description, with the protected Base layer pinned first — it carries config-as-code parameter defaults and can’t be deleted
- How many policies are active, running, and adaptive, plus completed and archived counts
- The top policies by priority with their state and traffic share
Creating a layer
New layer opens a dialog that starts with a template. The template decides what the layer is created with, and the form only asks what that template needs:- Feature flag — one parameter and a policy named
Feature flag — <flag name>serving its on value to every bucket. Asks for the flag name, the key (a parameter group plus asnake_casesuffix), the type, optional allowed values, the off and on values, and whether to turn it on right away. - Standard — one draft policy covering 100% of buckets and no parameters. Add parameters, then stack rollouts, A/B tests, and adaptive policies in priority order.
- URL redirect — a
redirect.urlparameter and an adaptive policy that splits visitors of one URL across alternative pages.
Layer detail
A layer’s page centers on its policies.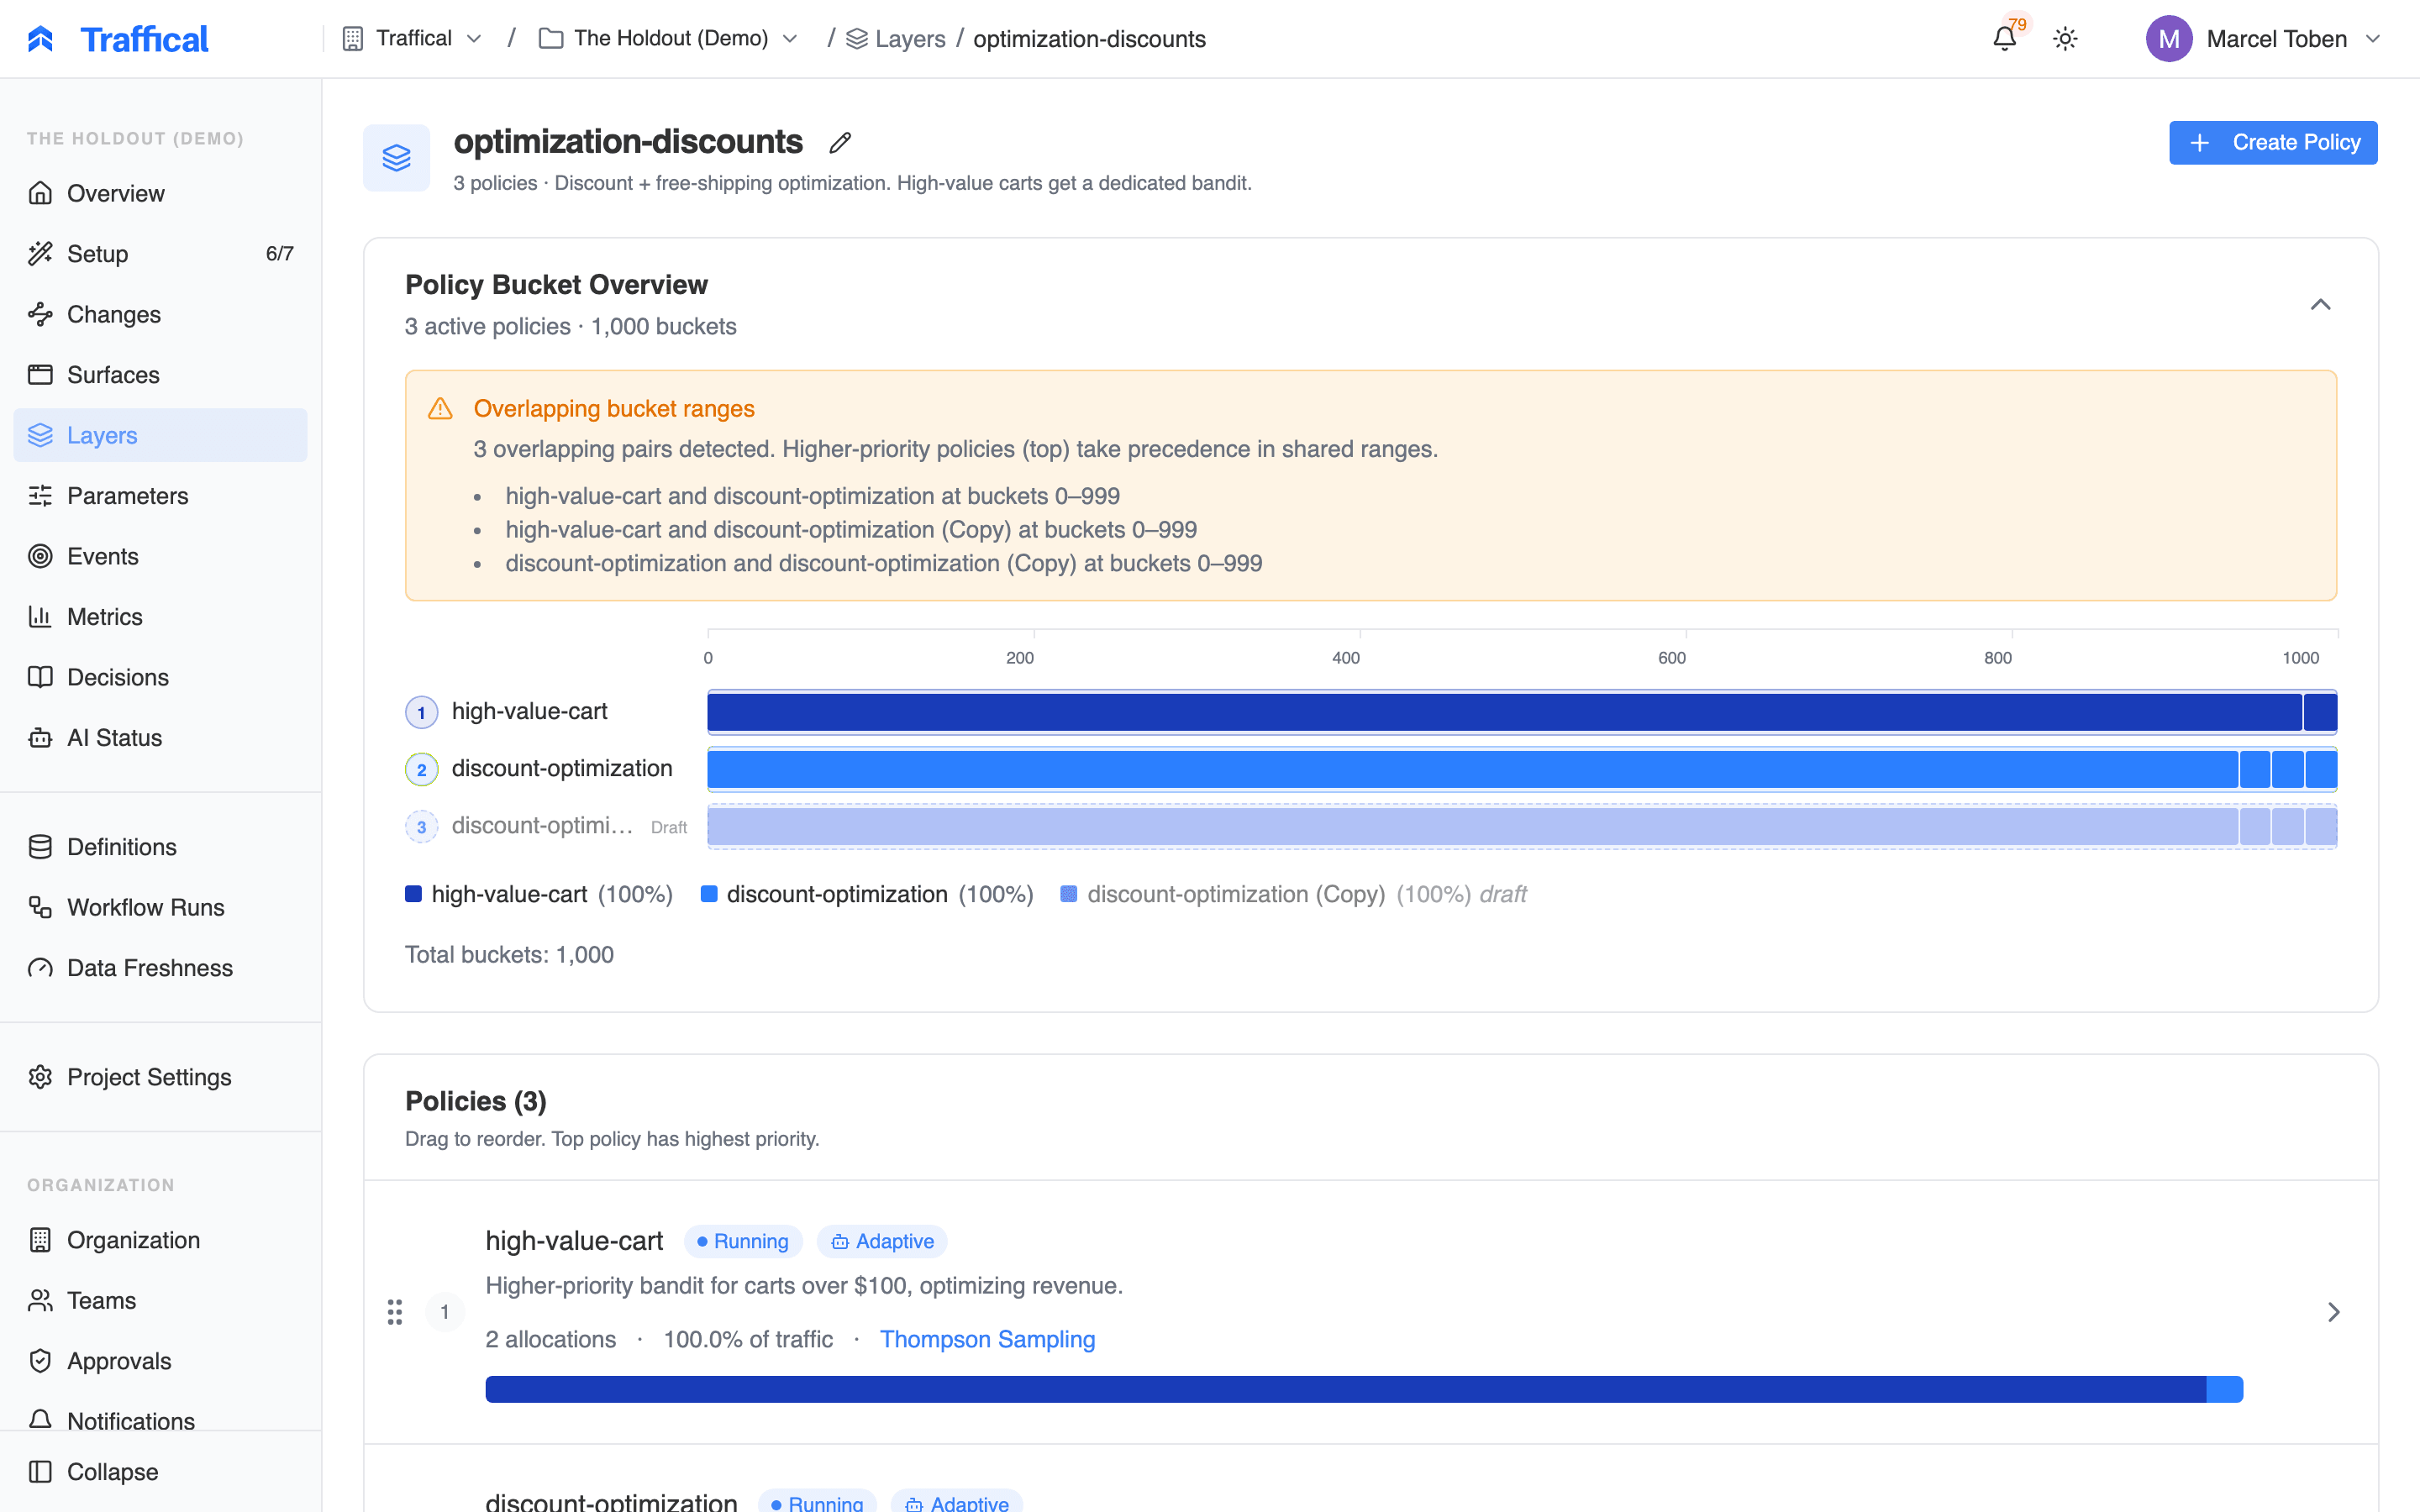
Layer detail — policies list and bucket overview
Policies list
Active policies are ordered by priority — when a user is eligible for more than one, the highest-priority eligible policy applies. Drag a row’s handle to reorder; the top policy has the highest priority. Each row shows:- Name, state (draft / running / paused), and kind (static / adaptive)
- An eligibility badge when the policy is restricted to a bucket range
- Allocation count, traffic share, and the algorithm for adaptive policies
- A live mini allocation bar for running policies
Swim-lanes view
Policy Bucket Overview draws every active policy as a lane across the layer’s bucket space, so you can see which bucket ranges each policy claims — and where eligible ranges overlap. Overlaps are flagged explicitly: when two policies draw from the same buckets, the higher-priority one wins for the shared users.Creating a policy
Create Policy opens a modal for the essentials: name, an auto-generated key (the stable identifier used in SDK events and warehouse assignment data), kind, the traffic split — defaulting to 50/50 Control / Treatment — the optimization goal for adaptive policies, optional targeting conditions, and optionally an eligible bucket range. The policy is created in draft — you configure parameter overrides for each allocation (and can refine splits and targeting) on its detail page before starting it. Creating and editing policies requires a role with policy write access — see Roles and permissions.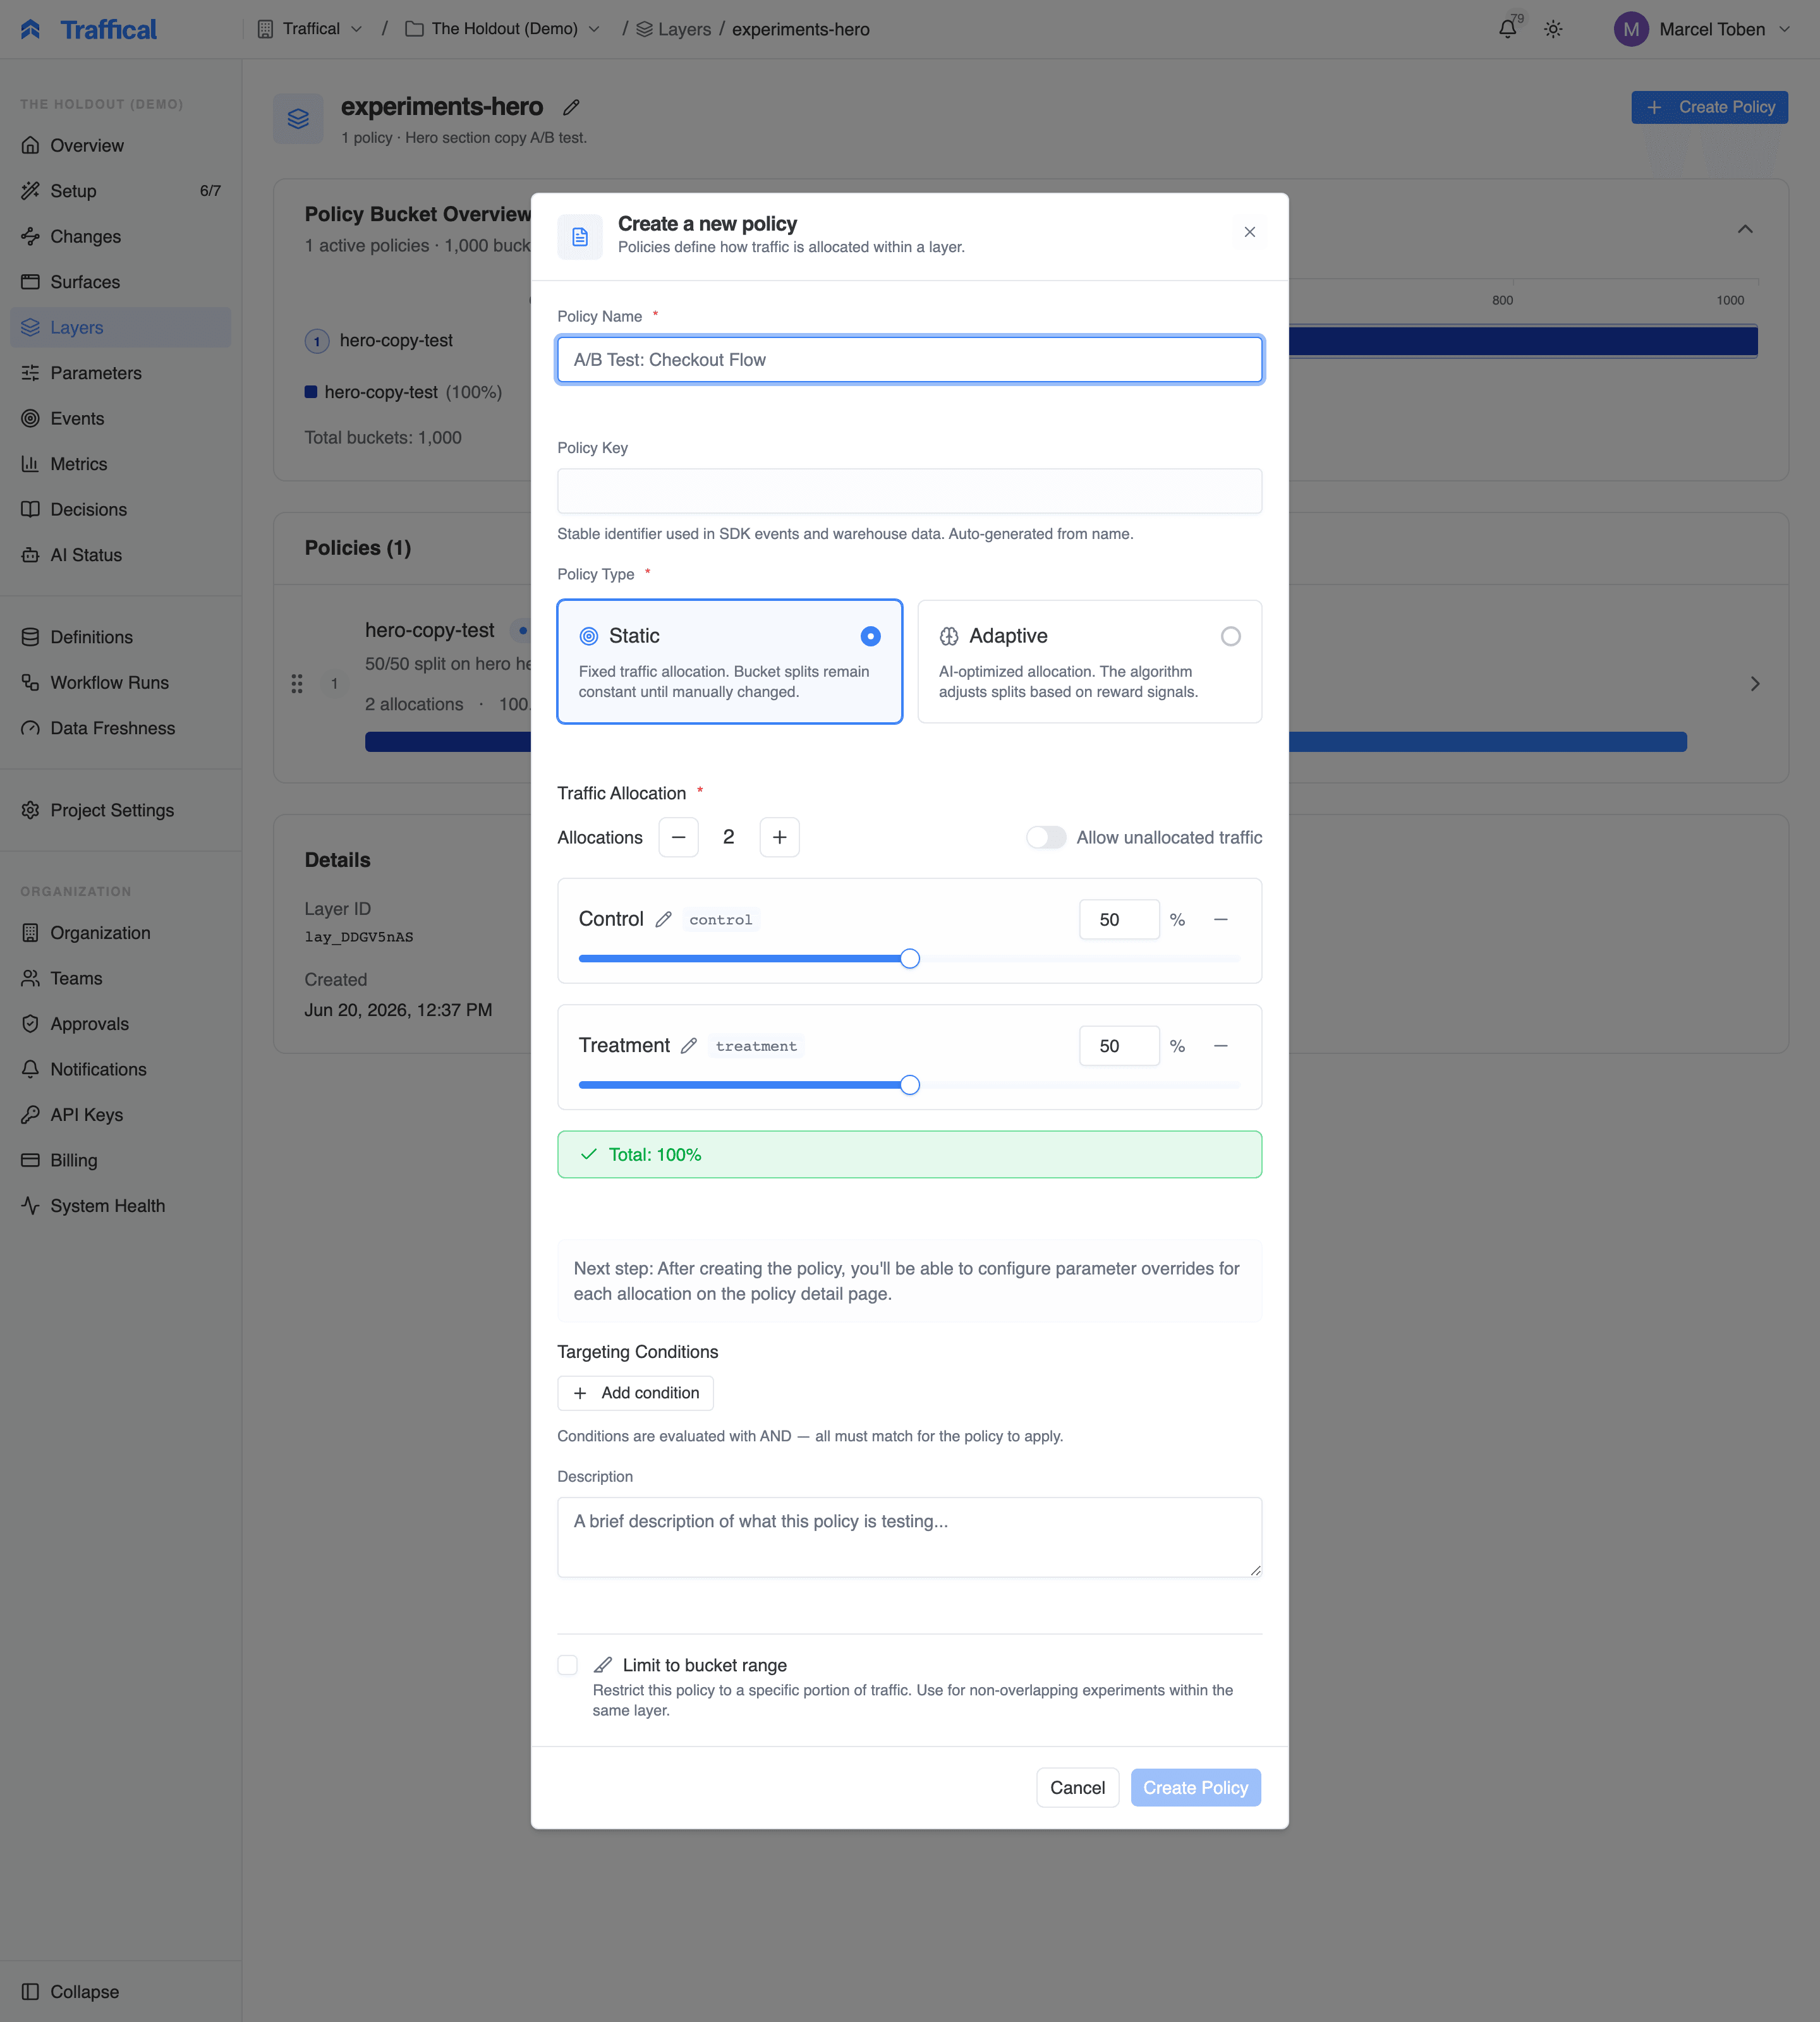
Create policy
Choosing the goal
Adaptive policies declare what they optimize in one of two modes:- Event mode — pick a goal event and a goal type: Conversion Rate, Sum, or Count (how the event aggregates per user). The selector previews the metric this resolves to — Optimizing metric: checkout_completed Conversion Rate — so the reward contract is explicit at authoring time.
- Metric mode — pick a goal metric directly from the project’s warehouse-native metrics (conversion rate, count, sum, or composite). The goal type follows the metric, certified metrics are labeled, and a metric with a decrease desired direction is minimized — the optimizer treats a drop as a win.
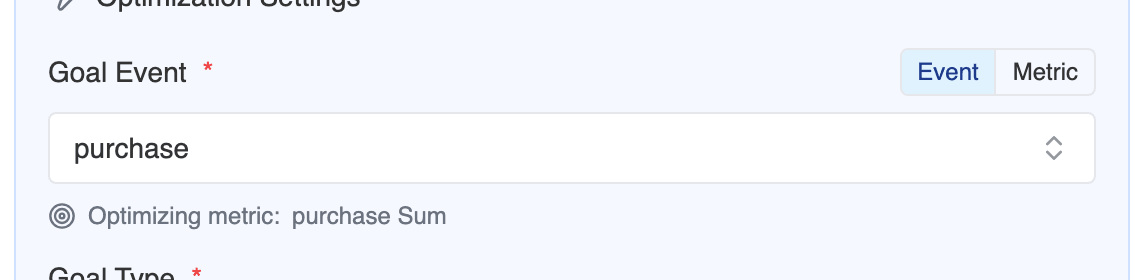
Goal selector
The policy detail page
The header carries the policy’s name, state, kind, and rollout status, plus the actions (below). Policies are often governed through a change — a banner links to the owning change, and standalone policies offer Convert to change. That lifecycle, including approval and autonomy rules, is covered in Changes in the dashboard, so it isn’t repeated here. Everything else is organized into seven tabs: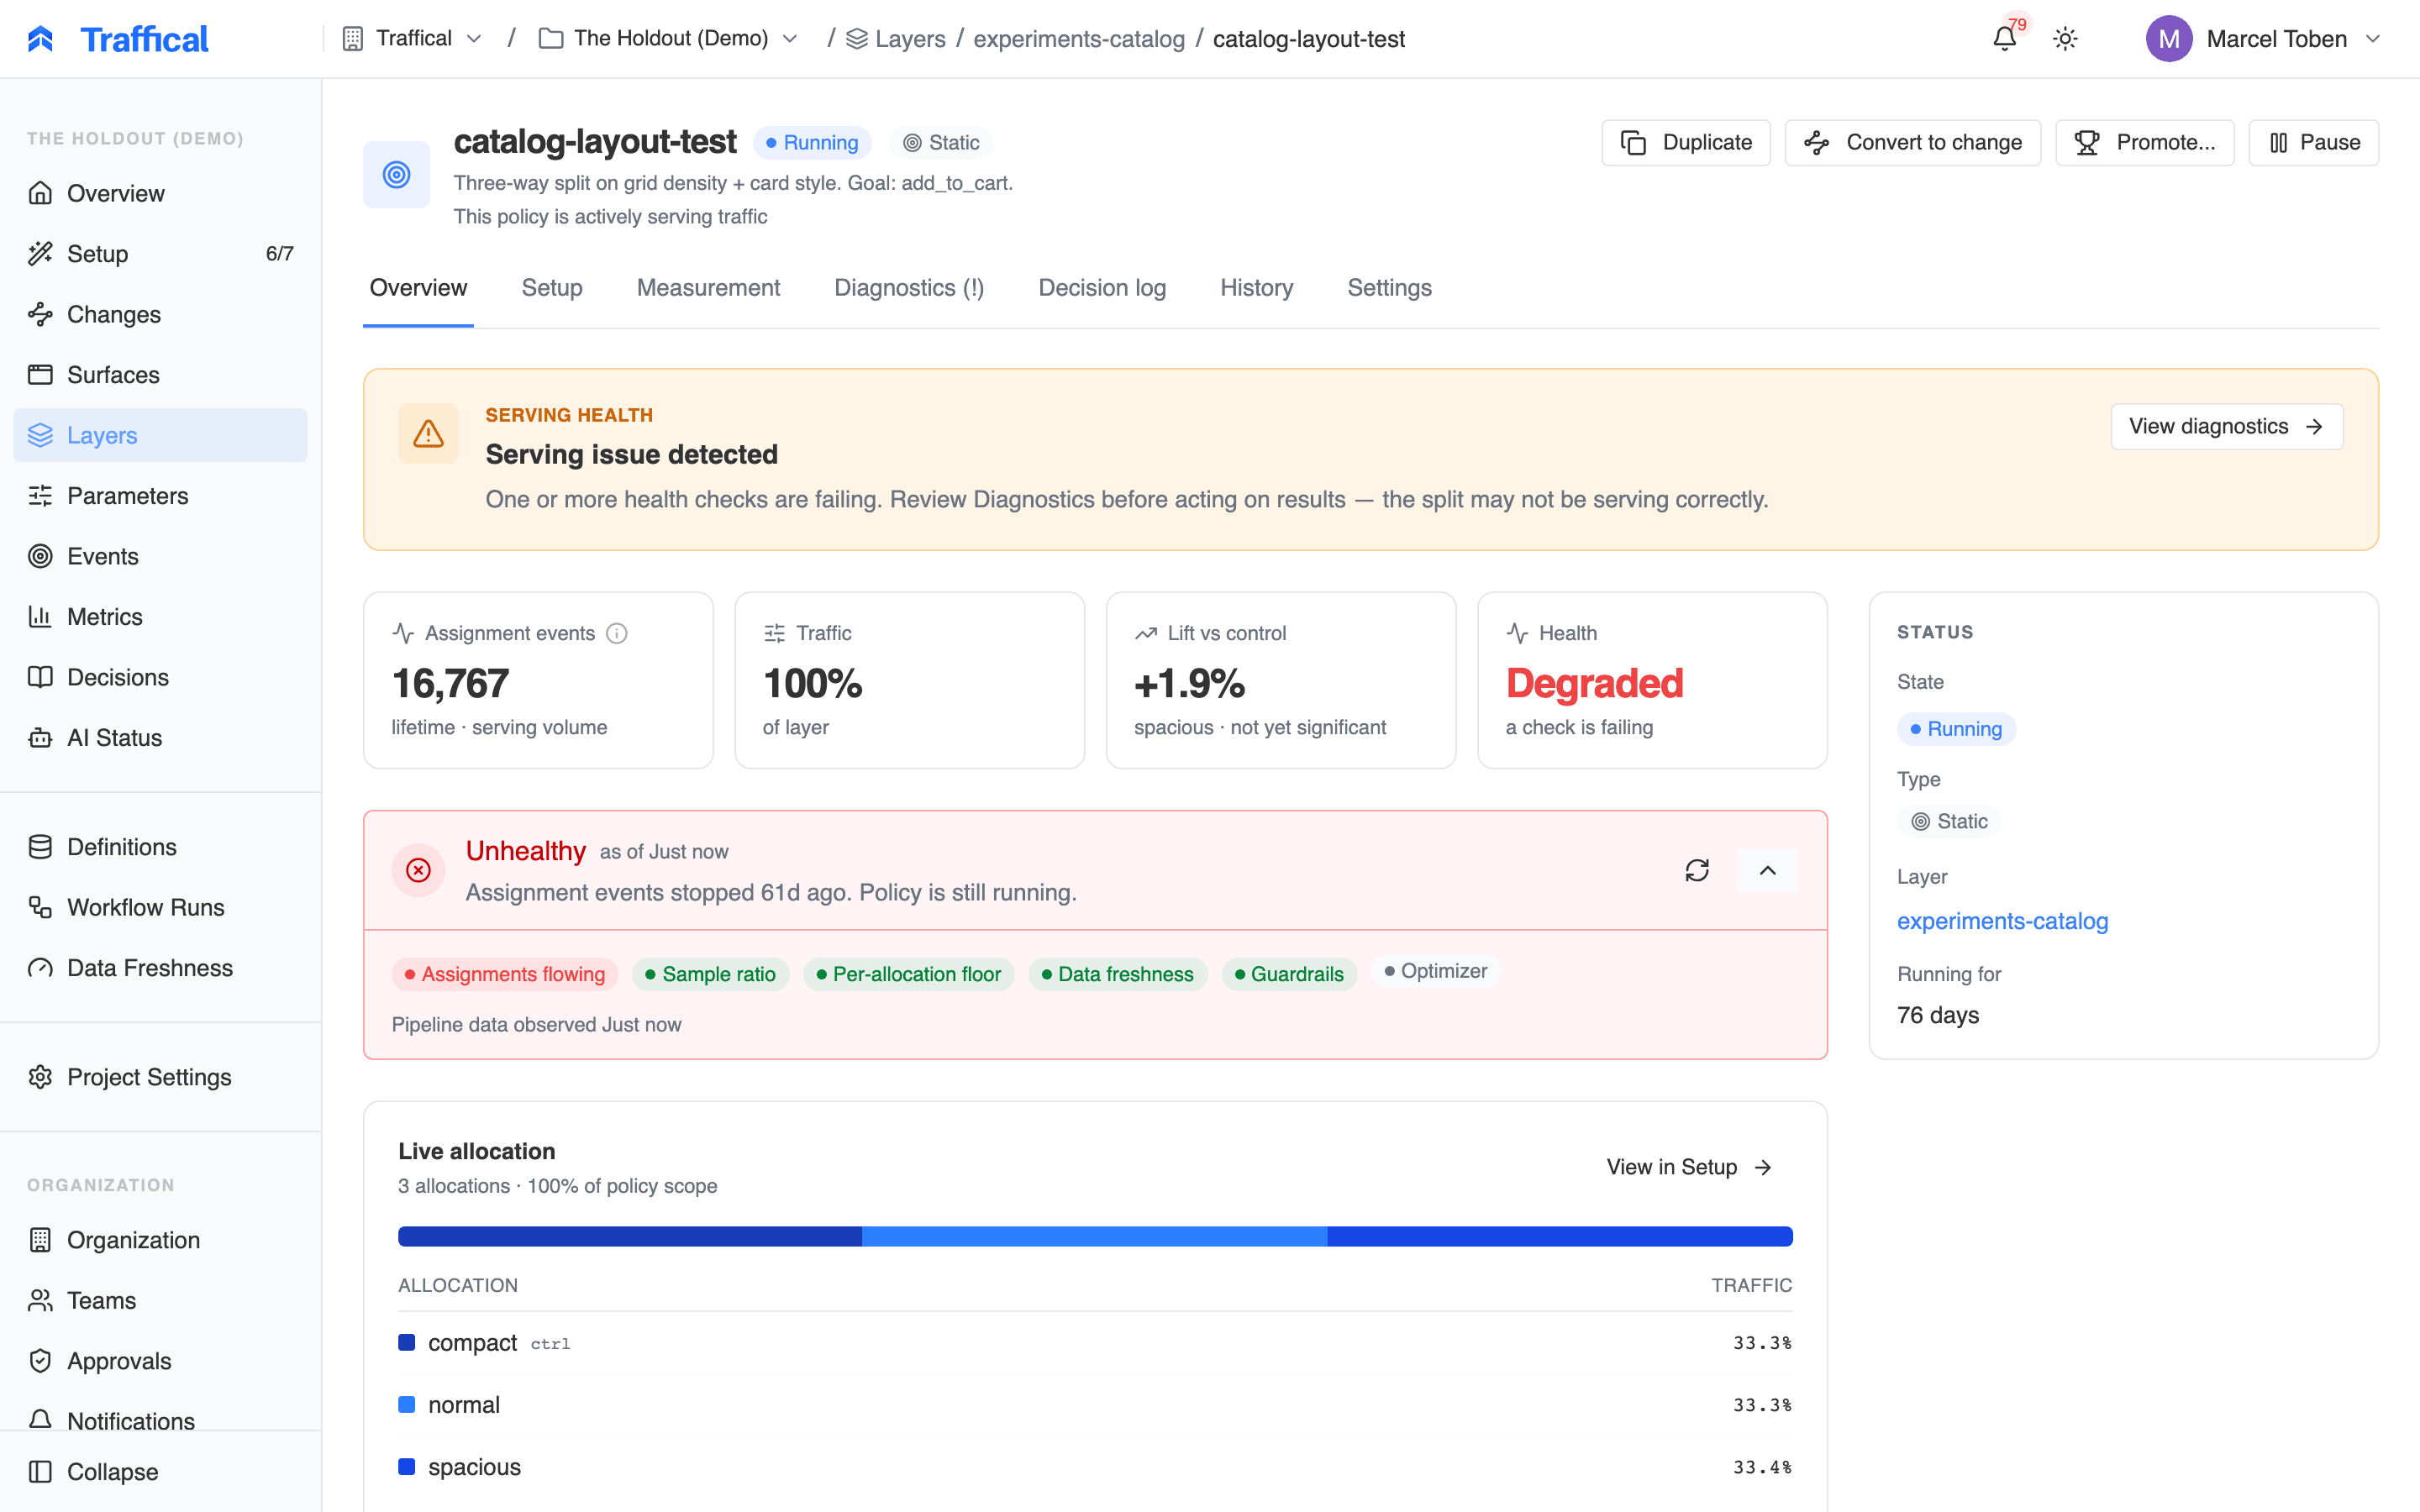
Policy detail — Overview
The verdict banner
A running policy opens with one plainly stated verdict. It is derived from real signals — serving health, the optimizer’s convergence, and the measured primary metric — and follows a strict precedence:- Completed outcome. A completed policy states its result — “checkout_v2 won” — with the final lift.
- Health breach. While any health check is failing, the banner reads “Serving issue detected” and points you to Diagnostics. No win is claimed and promotion is suppressed — the split may not be serving correctly, so results can’t be trusted yet.
- Winner. An adaptive policy whose optimizer has converged on a leader, or a static policy with a statistically significant measured winner.
- Still learning. No significant winner yet — the banner names the trending allocation, if any, and tells you to keep running.
- A bandit leader whose measured lift isn’t yet significant reads “X is winning traffic”, not “X is winning”. Winning traffic is what the optimizer did; winning is a measured verdict.
- Promote is offered only when it’s safe: it’s withheld while health is degraded or while measured significance is pending, with the banner telling you to resolve the health warning or keep running first.
- Only without a primary metric attached does the optimizer’s convergence alone carry the verdict.
Overview tab
A draft policy’s Overview shows a launch-readiness checklist, the planned traffic split, and a configuration summary — everything to review before starting. Once running, the Overview answers “where does this stand” without a tab switch:- KPI band — four numbers: lifetime Assignment events (serving volume — decision and exposure rows, repeats included), Traffic (the share of the layer’s buckets the policy’s allocations cover), Lift vs control, and Health. With a primary metric attached, the lift KPI shows the measured lift of the best challenger; it stays uncolored and flagged “not yet significant” until the result is conclusive, and the sign of a win follows the metric’s desired direction. Without a metric it falls back to the optimizer’s estimate.
- Serving health — the compact health summary; each check opens its history. See Policy health.
- Live allocation — the current split bar plus a per-allocation digest: traffic share, assignment events, and average reward or conversion rate for adaptive policies, with the leader badged. Completed policies show the final split.
- Primary metric strip — measured results per allocation against control with confidence-interval bars. This is the same snapshot the Measurement tab renders, kept separate from the optimizer’s learning signal so measured truth and bandit estimates never blur into one card.
- Rollout progress while a rollout is ramping, and — on completed policies — a How it closed card with the closing decision record.
Setup tab
Setup is the configuration home:- Configuration — algorithm, goal, minimum exposure events before traffic shifts, and context fields for contextual policies. Editable while in draft.
- Splits & parameters — the allocation bar (toggle between policy scope and layer scope) and the per-allocation parameter override editor. Once a policy starts, splits and overrides are locked for assignment stability — the optimizer owns the live split. Duplicate the policy to iterate.
- Measurement targets — the resolved target MDE per attached metric, each with a source badge showing where the value came from (policy override, metric default, project default, or assumed). Targets stamped by a measurement protocol are locked and change only through a protocol amendment. Guardrail metrics target their threshold instead — no MDE needed.
- A rail summarizes the rollout configuration (ramp, status, on-violation behavior) and the model for adaptive policies.
Measurement tab
Measurement is where you read results.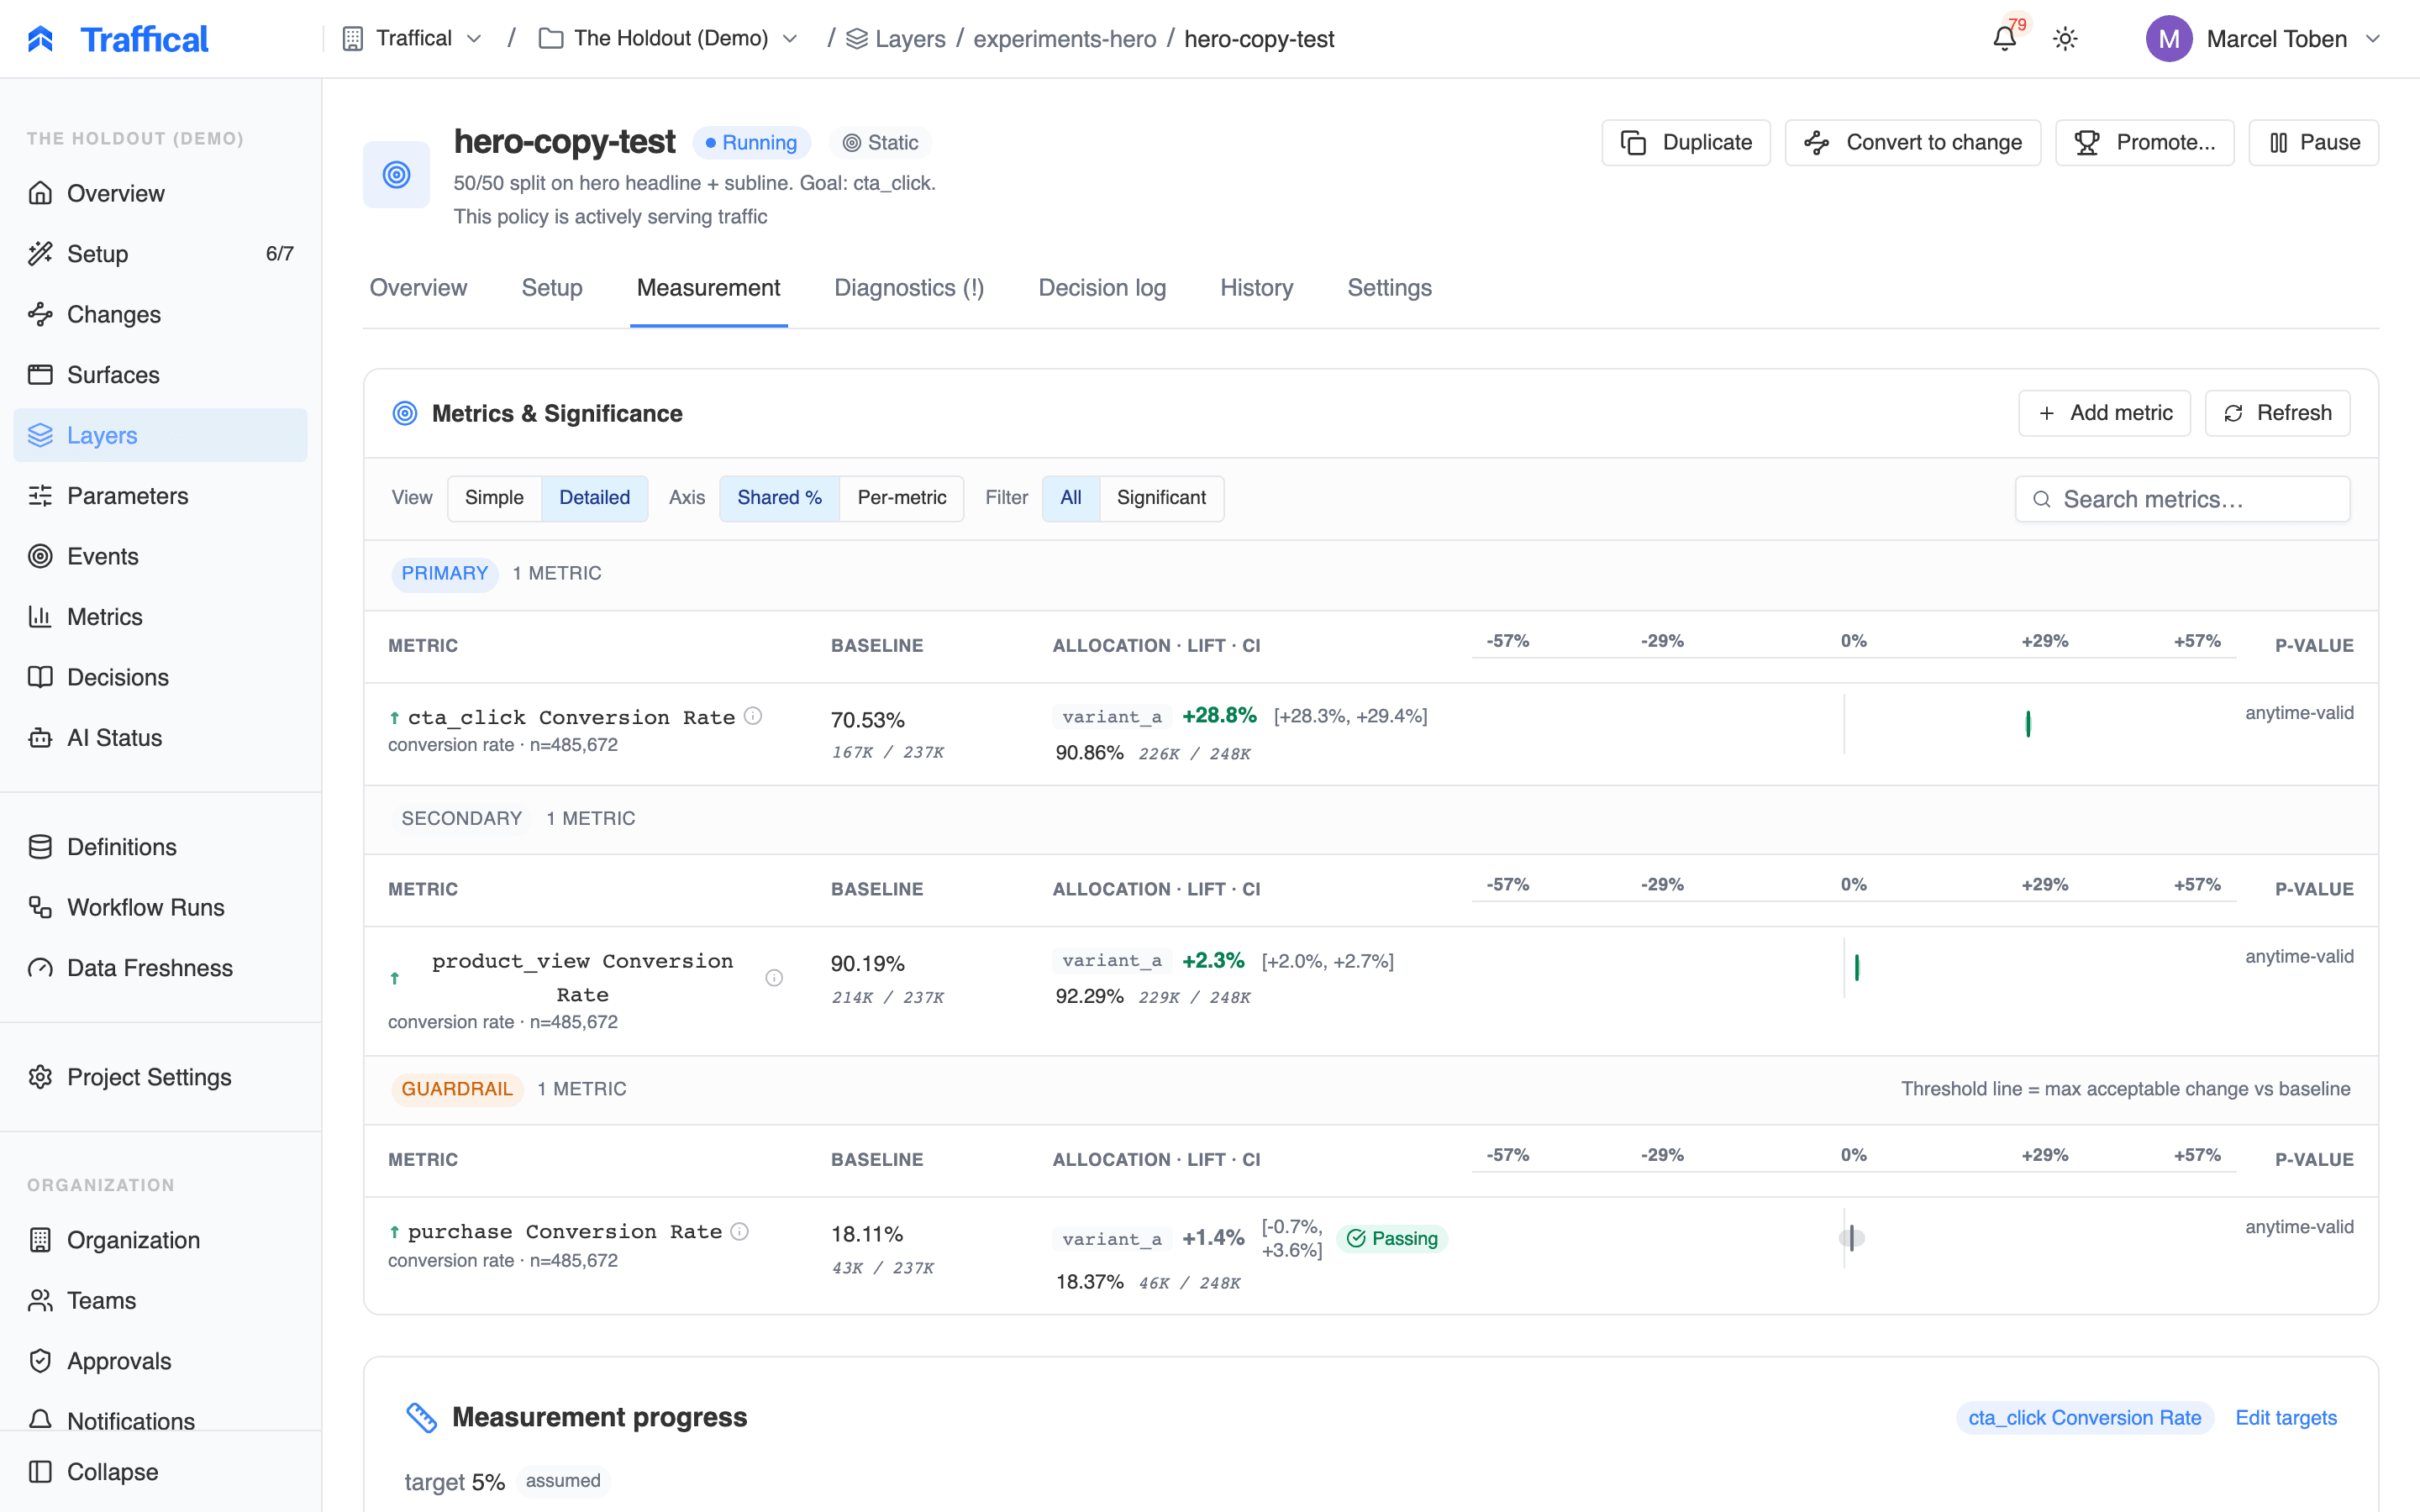
Policy detail — Measurement
Measurement progress
The measurement progress card tracks how close the measurement is to its target minimum detectable effect:- The target MDE with its source, a progress bar, and a Target reached terminal state
- Detectable now — the effect size the current enrolled units could reliably detect, converging toward the target
- An estimated time remaining with its as-of time — or an honest “no traffic accruing recently” when nothing is arriving
- For static tests with more than two allocations, the limiting allocation that gates overall progress
- When an entry point is attached, sizing and projections run on qualified units — enrolled units that reached the entry point — with the planned qualification rate shown alongside
- For adaptive policies, progress is measured on the leader-vs-control pair — the comparison that actually gates completion; contextual policies get no runtime estimate, since winners vary per context
Diagnostics tab
Diagnostics answers “is it serving correctly”:- Health checks as clickable pills — each opens its per-window history
- The assignments chart — assignment events and traffic share over a selectable window
- For static policies, an SRM history chart tracking sample-ratio mismatch over time
- Recent transitions — every per-check pass / warn / fail change
(!) whenever health is anything other than healthy — a warning is enough to flag it, not only a failing check. The checks themselves are documented in Policy health; if a check is failing, see Troubleshooting.
Decision log tab
A timeline of decision records for this policy: state transitions are captured automatically, promotions record their outcome (winner selected, inconclusive, reverted, …) with reason and tags, and Add Annotation lets you record checkpoints and context manually. This is the same data as the project-wide decision log, scoped to one policy.History tab
History is the raw evolution record:- Rollout history — every ramp step with from/to percentage, trigger (auto, scheduled, manual), and the health status at that step
- Optimization run log — each optimizer evaluation for adaptive policies
- Allocation history — how the split moved over time as the engine learned
- Change history — the configuration activity log
Settings tab
- Policy key — copy the stable identifier used in SDK events and in your warehouse
policyKeycolumn mapping. - Analysis — per-policy overrides for CUPED variance reduction and sequential testing. Each is a three-way choice: Inherit project default, Enabled, or Disabled, with the effective value spelled out (“Inherit (On)”). The effective rule is policy setting if set, otherwise the project default — see CUPED and Sequential testing.
- Bucket range — a readout of the eligible bucket range and the traffic portion it represents.
- Live edits — which parts of the policy may change while it is running or paused: targeting conditions, allocation values, or neither. Everything is frozen at start unless declared here, so measurement stays comparable; the traffic split always moves through the rollout controls. A live edit asks for a reason and writes it to the audit trail and, by default, the decision log. Feature-flag On policies and rollouts are created with targeting open; A/B tests with nothing open.
- Health checks — which health checks notify for this policy, layered on the project’s settings: Inherit, Alert, Monitor (badge and history, no notification) or Off per check. A policy operated by hand — a flag’s policy, a rollout, a QA policy targeting one user — may legitimately see no assignments for hours, so those are created with Assignments flowing and Per-allocation floor at Monitor. Delivery timing stays a project setting under Project Settings → Policy health.
- Targeting conditions — the eligibility rules, matched against the context your SDK passes at decision time. Conditions are combined with AND. Editable in draft, and while running when the policy’s Live edits setting allows it; see targeting conditions for the operators.
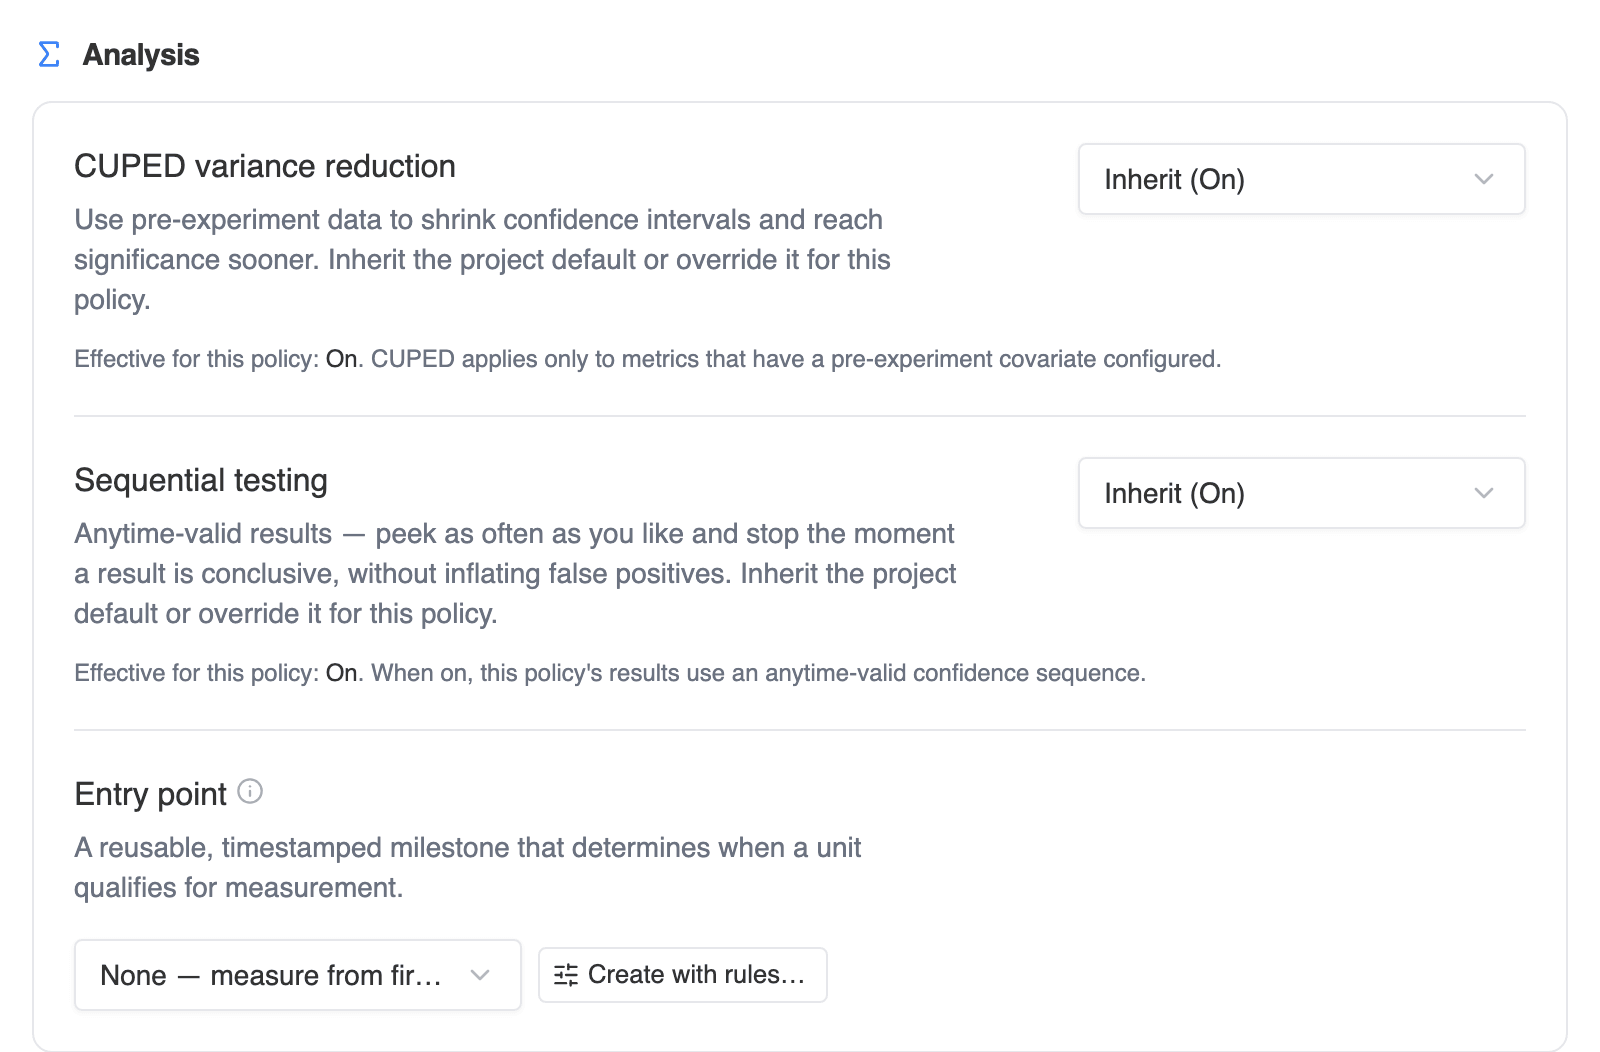
Policy settings — analysis overrides
Policy actions
From the header you can:- Start / Pause / Complete — completing is final: the policy stops being evaluated and its results are preserved.
- Promote… — available on running policies with two or more allocations and no active rollout, and from the completed verdict banner. Promoting creates a new static draft policy serving the winning allocation, with a rollout pre-configured to complete the source policy when it finishes — so the winner ships behind health gates. It writes a decision record to the source policy’s timeline.
- Duplicate — fork the configuration into a new draft. This is the way to iterate, since splits and overrides lock once a policy starts.
- Convert to change — wrap a standalone policy in a change.
- Configure Rollout — attach a progressive rollout while in draft; see Rollouts.
- Archive — draft and completed policies only.
Tips
- Always start in draft. Build out the allocations and conditions, then start when you’re ready. Switching state is fast; a misconfigured running policy is a panic.
- Use the eligible bucket range for non-overlapping policies rather than separate layers. Layers are for parameters; ranges are for sub-segments of the same layer. The swim-lanes view shows you exactly what overlaps.
- Attach a primary metric to adaptive policies. Without one, the optimizer’s posterior is the only signal and no measured verdict gates promotion. With one, you get the full standard of evidence.
- Name allocations descriptively.
controlandtreatmentare conventional, butlow_price_5is more useful thantreatment_bsix months later.
Next steps
A/B testing
Walking through a static policy end-to-end.
Optimization
Adaptive algorithms, contextual bandits, per-entity bandits.
Measurement progress
The math behind targets, detectable effects, and runtime estimates.
Policy health
Diagnostics for running policies: SRM, freshness, guardrails.
Decision log
The audit trail of every policy lifecycle action.
Impact methodology
How concluded decision records roll up into reported impact.